Speech Representation Learning and Model Analysis
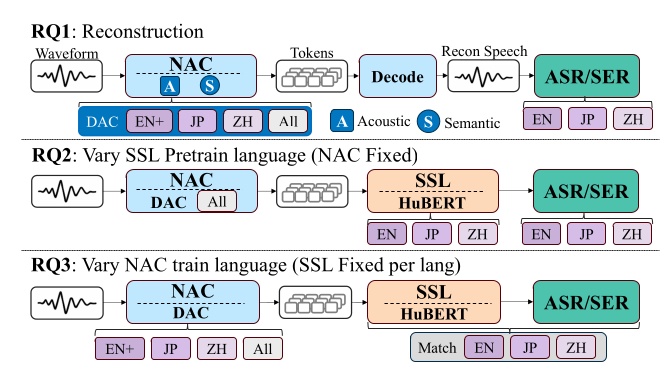
We investigate learned speech representations and efficient speech modeling, including self-supervised and generative spoken language models. Topics include extracting discrete speech units using independent component analysis (ICA), comparing phonetic and semantic information in representations, analyzing sensitivity to pretraining languages with neural audio codec tokens, and studying how generative spoken language models encode noisy speech. As a separate research direction, SelfRemaster addresses self-supervised restoration of degraded recordings, especially historical audio, using analysis-by-synthesis with source, filter, and recording-channel modeling without paired clean references.
The speech-representation studies include joint work with Prof. Shinji Watanabe (CMU)
Related Publications
- Daigo Takizawa, Tomohiko Nakamura, Samuele Cornell, William Chen, Satoru Fukayama, and Shinji Watanabe, “Dissecting sensitivity to training language in self-supervised speech learning using neural audio codec tokens,” in Proceedings of INTERSPEECH, Sept. 2026, pp. 7274–7279.
- Tomohiko Nakamura, Kwanghee Choi, Keigo Hojo, Yoshiaki Bando, Satoru Fukayama, and Shinji Watanabe, “Discrete speech unit extraction via independent component analysis,” in Proceedings of SALMA: Speech and Audio Language Models - Architectures, Data Sources, and Training Paradigms, IEEE International Conference on Acoustics, Speech, and Signal Processing Workshops, Apr. 2025.
- Kwanghee Choi, Ankita Pasad, Tomohiko Nakamura, Satoru Fukayama, Karen Livescu, and Shinji Watanabe, “Self-supervised speech representations are more phonetic than semantic,” in Proceedings of INTERSPEECH, Sept. 2024, pp. 4578–4582.
- Takaaki Saeki, Shinnosuke Takamichi, Tomohiko Nakamura, Naoko Tanji, and Hiroshi Saruwatari, “SelfRemaster: Self-supervised speech restoration for historical audio resources,” IEEE Access, vol. 11, pp. 144831–144843, Jan. 2024.
- Joonyong Park, Shinnosuke Takamichi, Tomohiko Nakamura, Kentaro Seki, Detai Xin, and Hiroshi Saruwatari, “How generative spoken language model encodes noisy speech: Investigation from phonetics to syntactics,” in Proceedings of INTERSPEECH, Aug. 2023, pp. 1085–1089.
- Takaaki Saeki, Shinnosuke Takamichi, Tomohiko Nakamura, Naoko Tanji, and Hiroshi Saruwatari, “SelfRemaster: Self-supervised speech restoration with analysis-by-synthesis approach using channel modeling,” in Proceedings of INTERSPEECH, Sept. 2022, pp. 4406–4410.